ACM SIGGRAPH · Motion, Interaction and Games 2022
SCOOT
Learning High-Risk
High-Precision
Motion Control
Learning to make precise decisions when a small error has irreversible consequences.
Aalto University, Finland
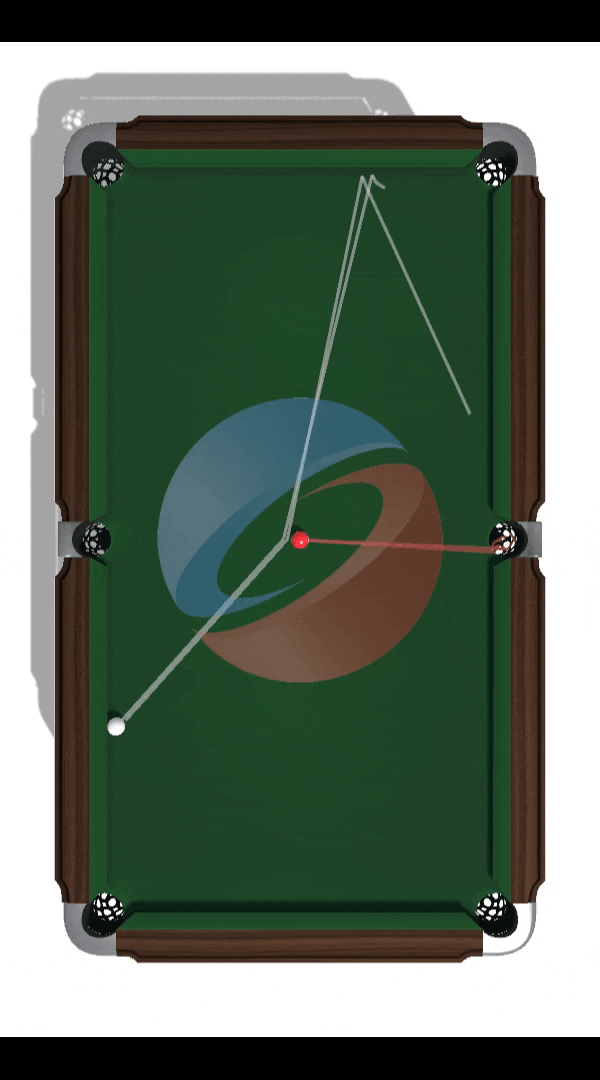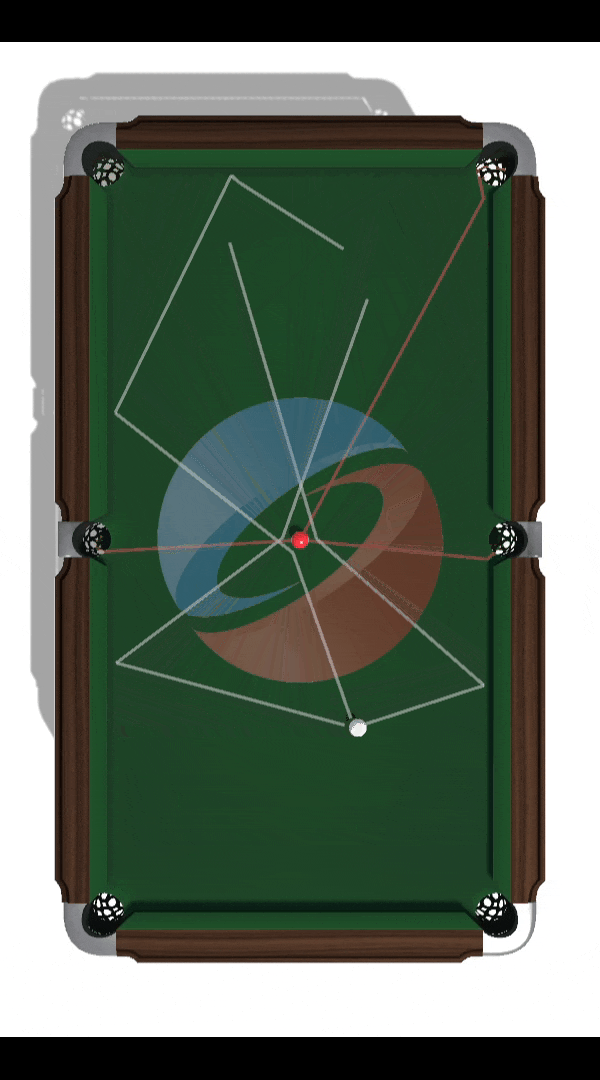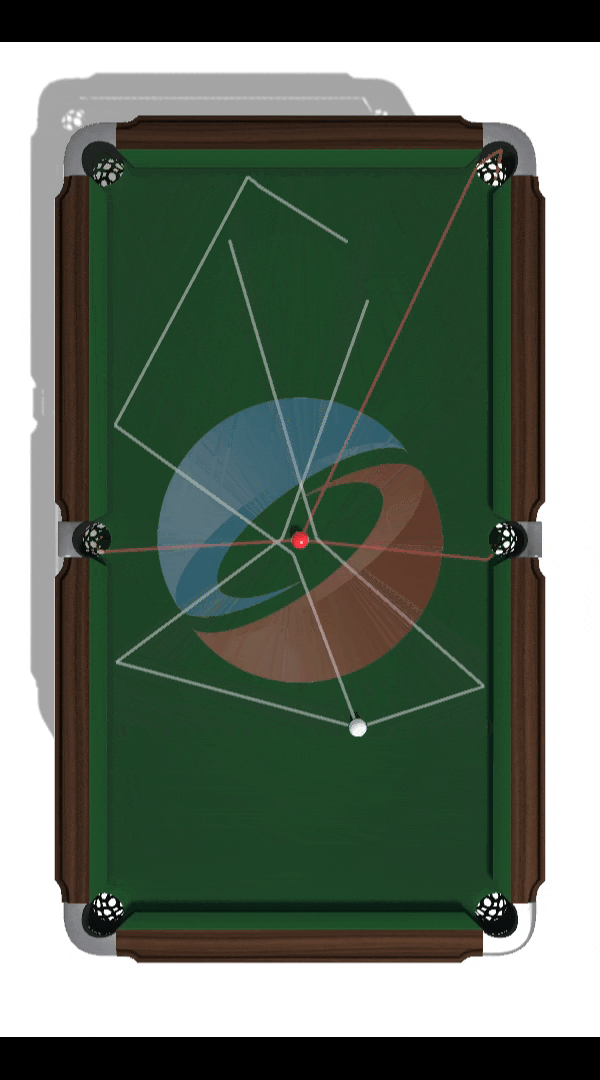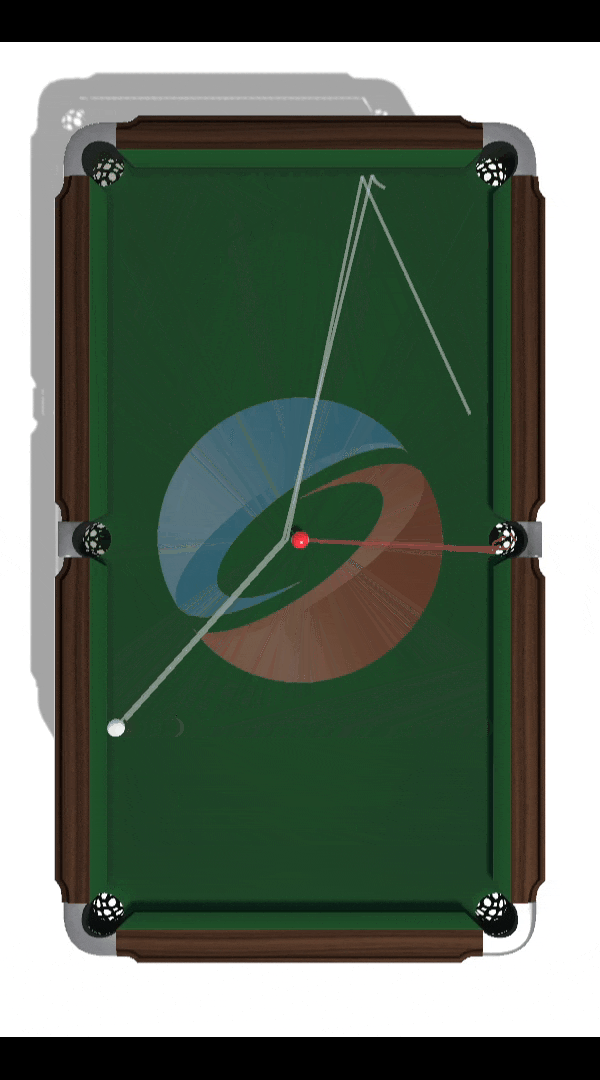
Precise learned shots.
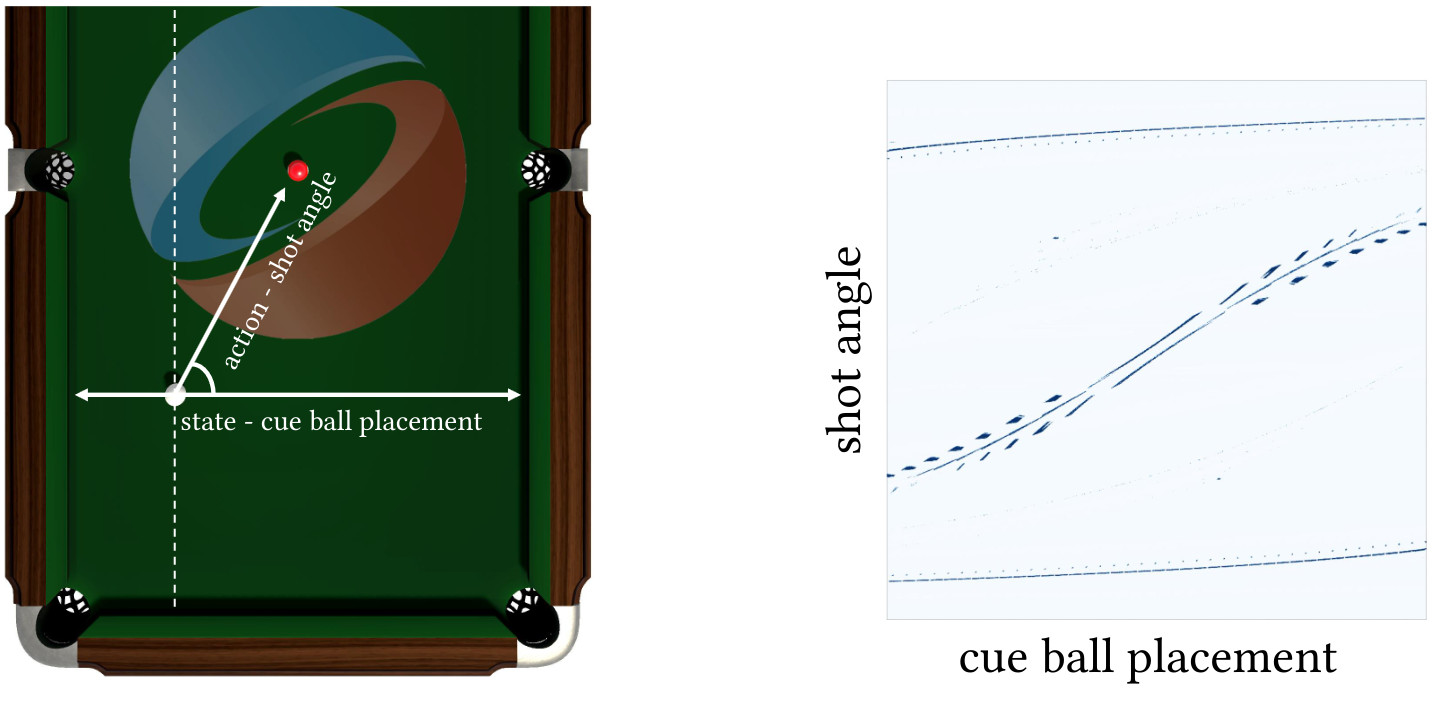
Deep reinforcement learning (DRL) algorithms for movement control are typically evaluated and benchmarked on sequential decision tasks where imprecise actions may be corrected with later actions, thus allowing high returns with noisy actions. In contrast, we focus on an under-researched class of high-risk, high-precision motion control problems where actions carry irreversible outcomes, driving sharp peaks and ridges to plague the state-action reward landscape.
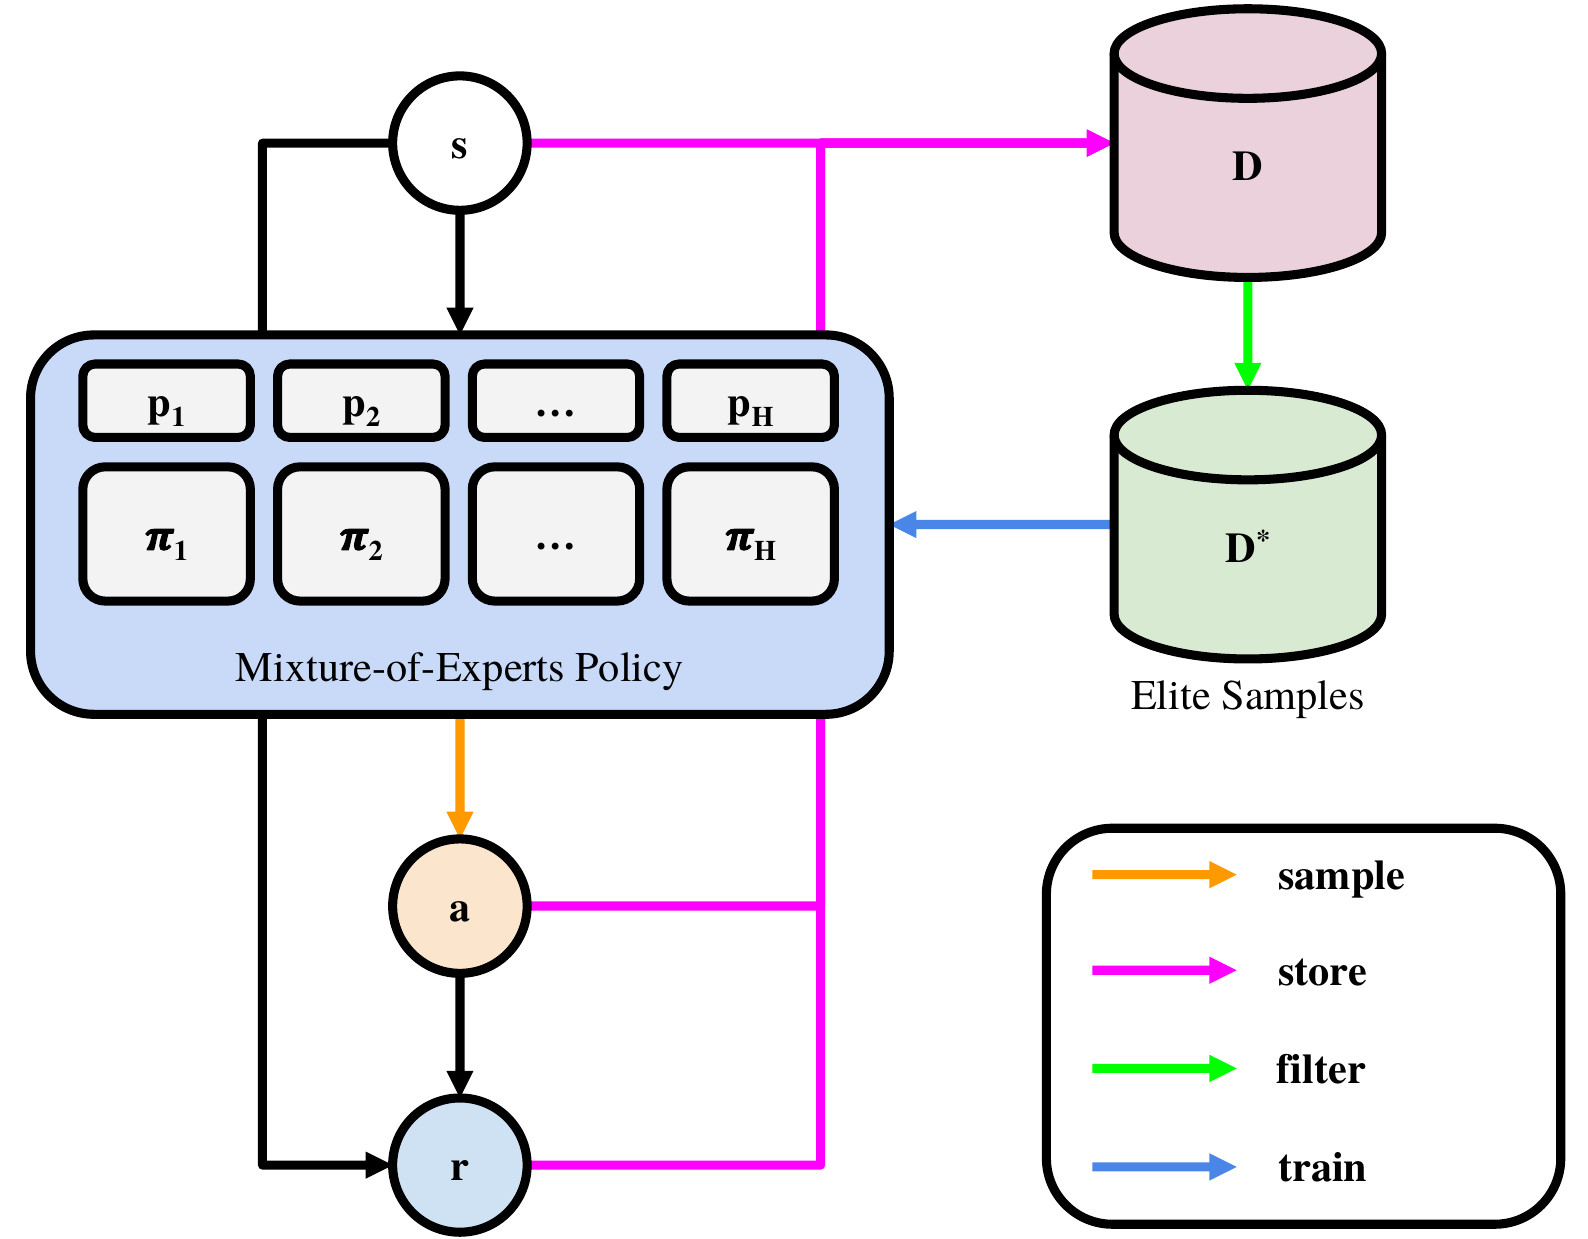
Using computational pool as a representative example of such problems, we propose and evaluate State-Conditioned Shooting (SCOOT), a novel DRL algorithm that builds on advantage-weighted regression (AWR) with three key modifications: 1) Performing policy optimization only using elite samples, allowing the policy to better latch on to the rare high-reward action samples; 2) Utilizing a mixture-of-experts (MoE) policy, to allow switching between reward landscape modes depending on the state; 3) Adding a distance regularization term and a learning curriculum to encourage exploring diverse strategies before adapting to the most advantageous samples.
We showcase our features' performance in learning physically-based billiard shots demonstrating high action precision and discovering multiple shot strategies for a given ball configuration.
01 / The challenge
A difficult reward landscape
In computational pool, a small change in cue-ball placement or shot angle can change the outcome. Successful shots lie on sparse, sharp, and multi-modal reward ridges.
02 / The approach
State-Conditioned Shooting
SCOOT builds on Advantage-Weighted Regression (AWR) with three modifications for high-precision motion control.
Learn from elite samples
Optimize the policy using only elite samples, so rare, high-reward actions guide learning.
Learn multiple strategies
A mixture-of-experts policy switches between reward modes depending on the state.
Explore before specializing
Distance regularization and a learning curriculum encourage diverse strategies before adapting to the most advantageous samples.
03 / See it in action
Watch the research video
High-precision control, demonstrated through physically simulated billiard shots.
Build on this work
Citation
If you use SCOOT in your research, please cite our paper.
@inproceedings{kim2022learning,
  title     = {Learning High-Risk High-Precision Motion Control},
  author    = {Kim, Nam Hee and Kirjonen, Markus and H{\"a}m{\"a}l{\"a}inen, Perttu},
  booktitle = {Proceedings of the 15th ACM SIGGRAPH Conference on Motion, Interaction and Games},
  pages     = {1--10},
  year      = {2022},
  doi       = {10.1145/3561975.3562943}
}